AI-ready documentationRequest a demo
Search
Search is unavailable. Enable JavaScript or try again shortly.
Documentation APIs for AI agents need approved content, product context and traceable sources.
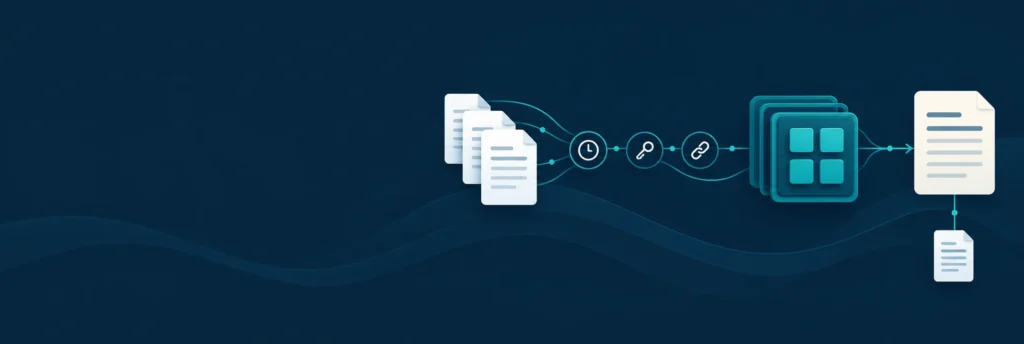
Reviewed content. A traceable version.
Product configuration. Warnings. Access.
Applicable guidance with a source reference.
Documentation APIs for AI agents should return approved technical content with its product and version context, access permissions, required warnings and source references. The interface connects systems; the content model and governance determine whether the answer is usable.
A service technician asks an AI assistant for the maintenance procedure for a machine on the factory floor. The assistant finds a clear, well-written answer in the company’s documentation. There is one problem: the procedure applies to a different configuration.
As AI agents become another way to access technical information, documentation teams need to think beyond whether a system can retrieve their content. They need to consider what the interface returns, which context travels with it, and how an answer can be checked.
Documentation APIs can make approved knowledge available to new applications. Their value depends on the content and controls behind that access. For complex products, that makes information architecture a practical part of the AI project.
A manual, customer portal and AI assistant may all need the same maintenance information. Maintaining separate copies for each channel increases the work involved when a product changes. Reusable content gives teams a common source they can review, update and deliver in different ways.
Headless delivery separates content services from a particular presentation layer. A support application can request content through an interface and present it within its own experience. A documentation portal can remain available alongside that approach.
This creates useful options for technical teams. The same approved source could support a technician’s portal and an assistant, provided the implementation preserves the right context and access controls. Separating delivery from presentation does not remove the need to govern what is delivered.
An API defines how software can request data or use a service. Documentation APIs for AI agents may expose publications, topics, search results or metadata, depending on the product and implementation. The presence of an API alone says little about whether those responses suit an AI application.
The Model Context Protocol, or MCP, provides a standardized way for AI applications to connect to external capabilities. MCP servers can expose resources, tools and prompts. A server may use an existing documentation API behind the scenes; teams still need to decide which operations to expose and how to authorize them.
Retrieval is another part of the design: finding and selecting the source material relevant to a request. Retrieval-augmented generation uses retrieved material to inform a generated response. Neither an API nor an MCP connection automatically makes that selection accurate.
These concepts work together, but they answer different questions. Headless describes the separation of content and presentation. APIs and MCP provide connection mechanisms. Retrieval determines which evidence is supplied, while the application decides how to use it.
Three terms, three different roles
These mechanisms enable access. Retrieval quality, product context and permissions still need to be designed and tested.
Technical content often carries conditions that change its meaning. A procedure may apply only to a particular product family, software version, region or service role. A warning may be essential to understanding the steps that follow it.
Consider a hypothetical packaging line with two control-system configurations. Both manuals contain a section called ‘Replacing the sensor’, but the approved preparation steps differ. Retrieving the closest wording without checking the configuration could return the wrong procedure.
A better workflow first establishes the machine configuration, asking the technician if necessary. It then retrieves the applicable approved procedure, includes required warnings and prerequisites, and provides a reference to the source. If the configuration cannot be established, the assistant should explain what is missing rather than improvise.
This is a design requirement to test. It should not be assumed from a polished demonstration or a connector’s feature list.
DITA supports topic-based content, reuse, metadata and conditional processing. These capabilities help teams represent information and its intended context consistently. A component content management system adds managed processes around that content, such as review, version control and release management.
For organizations with many product variants and shared procedures, this can provide a useful foundation for agent access. A reused warning can be managed at its source. Applicability can be represented explicitly instead of being left for a downstream system to infer from prose.
Different teams can meet these requirements with different architectures. The buying question is whether the chosen approach can maintain identity, relationships, applicability and approval state as content changes, and what work is required to do so.
A real manufacturing example
Bluestream’s Life Fitness case study describes a move from PDF-only manuals to online content that service technicians could use on phones and tablets. Its support teams also linked documentation topics from Salesforce articles. This illustrates the value of reusable, addressable technical content; the case study does not describe an AI-agent deployment. Documentation APIs for AI agents build on that content foundation, with additional retrieval, permissions and evaluation work.
An assistant may bring together documentation, service information and other business data. Each source still needs an owner and a clear access policy. Connecting repositories should not give users access to material they could not otherwise see.
Reading a procedure and changing a business record also require different controls. If an agent can create a service request or update a system, define the permitted actions and any approval needed separately from its ability to retrieve content.
Plan for change after launch. When a procedure is revised or withdrawn, determine how caches and retrieval indexes are updated. Record enough source information to investigate an answer, including which content version supported it. Agree what happens when a source is unavailable.
A useful evaluation should follow a real support question through the complete workflow. Ask documentation, IT and service teams to agree the expected result, then test difficult cases alongside straightforward ones.
Can the system distinguish similar procedures for different products or versions?
Can the user trace the response to the approved source and its version?
Are required warnings and prerequisites included in the retrieved context and preserved in the response, with access to related material?
Are restricted sources excluded for a user who lacks access?
What happens after a correction, withdrawal or permission change?
Does the assistant ask for missing context or explain when the evidence is insufficient?
Who owns failed requests, monitoring, interface changes and ongoing evaluation?
Measure the outcomes that matter to the workflow: correct source selection, handling of ambiguous questions, access-policy failures and time needed to find a usable answer. Keep human review in the pilot, and define the ongoing review or approval required for safety-critical guidance and actions.
XDocs DITA CCMS supports reusable technical content, metadata, versions, review workflows and localization. Its standards-based APIs provide integration options for external systems. XDelivery offers documentation delivery through a portal and supports headless integration into existing sites.
These capabilities provide a starting point for connecting governed technical content to other experiences. Any AI implementation still needs its own retrieval design, permissions, evaluation and integration work. The specific interfaces and workflow should be confirmed for the intended environment.
Start with one product family and a small set of support questions. Prove that the right approved content reaches the right user, including when context is missing or a procedure changes. That gives the team a sound basis for expanding access.
Talk to Bluestream about the content structure and delivery requirements behind your next documentation integration.
Source: Adapted from Andrew Douglas’s original LinkedIn article.
Tell us about your content, products and delivery needs. Request a demo to explore how XDocs and XDelivery could fit your documentation workflow.
Type at least two characters or choose a filter to browse.