Context-aware documentation

Why Your Technical Documentation Needs Personalization

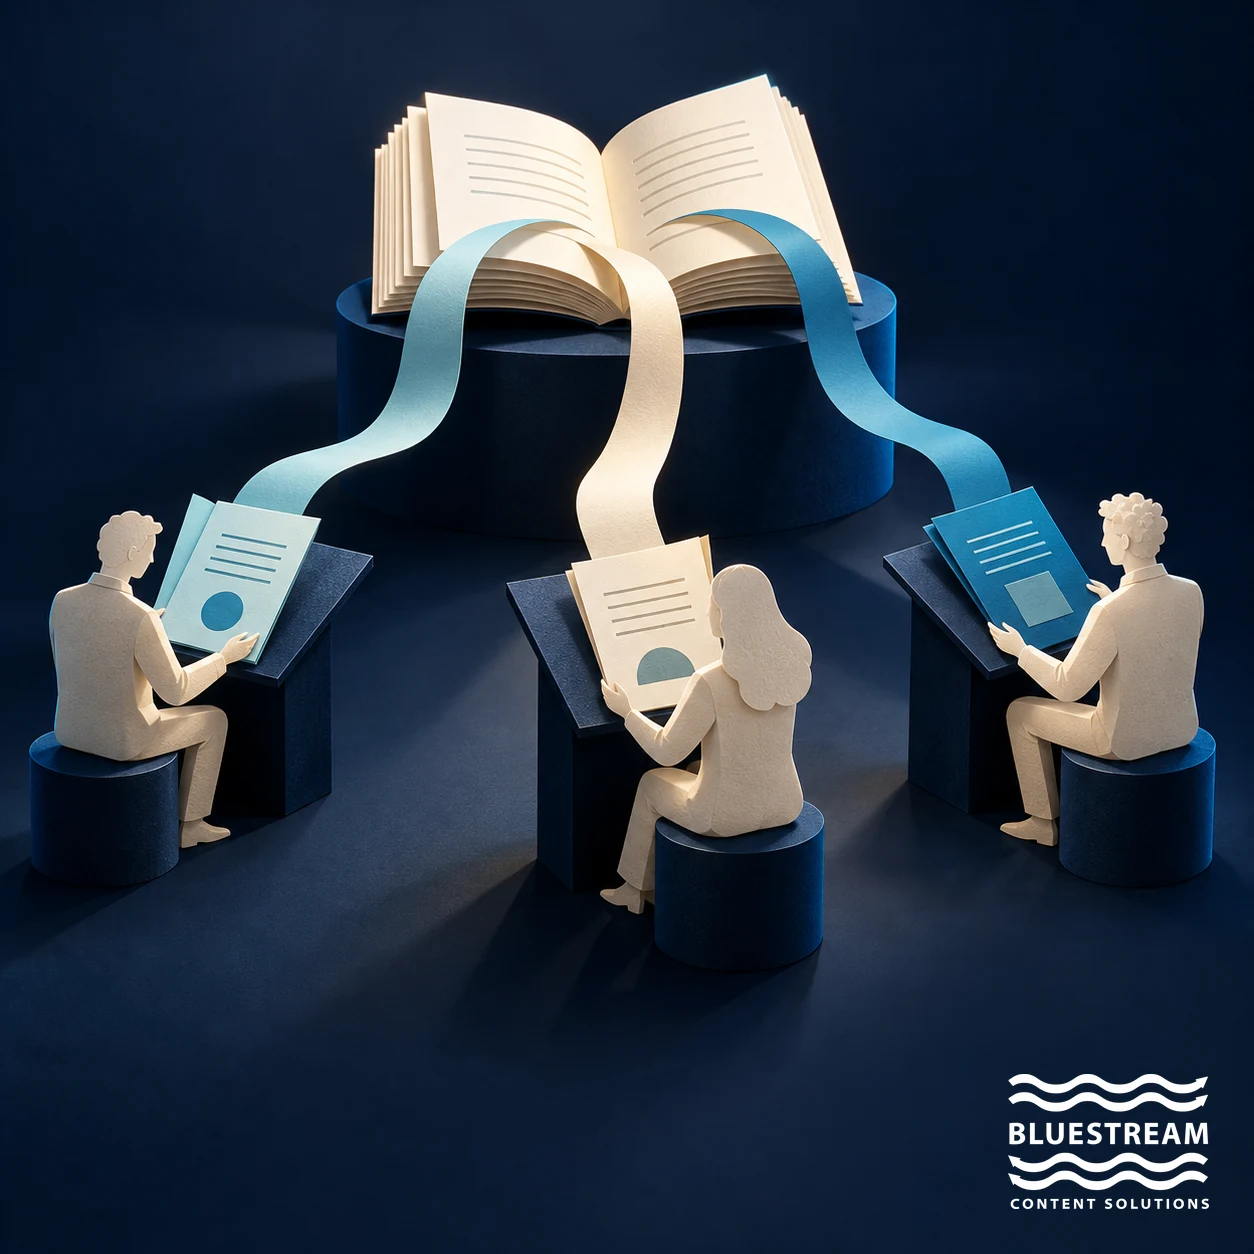
Three readers receive different sections from one shared source, illustrating personalized technical documentation.

Choose useful contextGovern metadataTest complete variants

Technical documentation becomes more useful when it matches the reader’s product, release, task, and working environment. A developer integrating an API, an administrator configuring access, and a field technician maintaining equipment may use the same product while needing very different information.

Personalization helps readers reach the relevant material with less sorting and interpretation. It can be as simple as a visible product-version selector or as involved as a collection assembled for an installed configuration. The goal is a clear, correct path to the task, with enough context for readers to understand why the content applies.

What personalization means in documentation

Documentation personalization adapts the selection, organization, or presentation of content to a reader’s situation. That situation may be declared by the reader, supplied by the product, or associated with an authenticated account.

Useful dimensions include the product being used, its release, the operating environment, the reader’s task, the language, and the installed options. Roles can help, but a job title is often less precise than a task. An administrator may need API information during automation work; a developer may need installation guidance during evaluation.

Start with the distinctions that change the instruction or the route to it. A long profile questionnaire is unnecessary if two visible selectors would get the user to the right procedure.

Personalization is different from access control

Personalization can prioritize relevant material within the content a reader may access. Authorization determines what that reader is allowed to receive. A portal that hides a partner-only manual from its homepage still needs to protect the manual’s direct URL, search results, downloads, and API responses.

Likewise, content tagged for engineers is not automatically confidential, and content shown to everyone may still need filtering by version. Define these concerns separately so relevance settings do not accidentally become security assumptions.

Choose the right level of personalization

Reader-selected filters

Product, version, and language selectors are a practical starting point. They are easy for users to understand and correct. Show the current selection on the page, preserve it across relevant navigation, and make it easy to return to a broader view.

Context supplied by a product

In-product help can open documentation for a known screen or software release. The integration should pass a stable topic identifier and the appropriate context. Define the fallback if the requested version or language is unavailable.

Account or installed-configuration context

A service portal may use a customer’s entitled products or an equipment configuration to narrow the collection. This requires trustworthy, maintained data and a clear relationship between the equipment, applicable documentation, and the person requesting it.

Do not treat an inferred preference as an established fact. A service technician may work on several machines, and a support agent may move between customer accounts. Make context changes visible and ensure one customer’s selection does not persist into another customer’s session.

How DITA supports targeted publications

DITA provides reusable topics and metadata that can support different publications from shared source content. Its metadata attributes include audience, product, and platform values that can participate in conditional processing.

For example, an author might identify material for administrators or for a particular operating environment. A publishing profile can then include the appropriate material in a defined output. The naming conventions and allowed values need to be agreed by the team, rather than invented independently in each topic.

Distinguish publishing-time filtering from delivery-time selection

A publishing pipeline may create an administrator guide and a developer guide as separate approved publications. A delivery system may instead use metadata to select among available topics or collections at request time. Some systems combine both approaches.

DITA markup by itself does not authenticate a reader or create a dynamic user profile. The processor and delivery platform must implement the intended behavior. Confirm where conditions are resolved and test the output rather than assuming that any attribute automatically becomes a live portal rule.

Reuse complete meaning

Reuse is most helpful when the shared content carries the same meaning in each context. Keep required warnings, prerequisites, and limitations with the instruction they qualify. Avoid assembling a procedure from fragments whose applicability becomes unclear when a filter removes the surrounding explanation.

Create a metadata model writers can maintain

For every personalization field, document its purpose, permitted values, owner, and default behavior. Explain when to apply it at the topic or publication level, and when a more granular condition is justified.

Build checks for missing values, inconsistent spellings, and incompatible combinations. If one writer uses “Windows” and another uses “win,” the delivery layer needs either a deliberate mapping or a validation error. Silent inconsistency makes the reader experience difficult to predict.

A useful metadata checklist asks:

  • Does this field change a real reader decision?
  • Can authors determine its value from an authoritative source?
  • Is the vocabulary small enough to govern?
  • What happens when the value is absent, outdated, or unknown?
  • How are inherited values and reused topics handled?
  • Who approves a new value or retires an old one?

Choose a content steward to own the vocabulary, with input from product, support, and localization teams. The role is to keep the model useful and understandable, not to add tags to every possible distinction.

Start with a small, representative pilot

Choose one product and a few high-value tasks. Include a shared topic, a genuine variant, an older supported release, and any access-restricted material needed to test the boundary. Record how readers find and use those topics before making changes.

  1. Identify the task and context. Establish which information changes between the selected audiences or environments.
  2. Audit the content. Separate reusable material from content that genuinely differs. Fix missing prerequisites before adding filters.
  3. Apply a small metadata set. Use controlled values and document the defaults.
  4. Configure the publishing and delivery behavior. Make the selected context visible and define a fallback for unsupported combinations.
  5. Test complete journeys. Include direct links, search, related topics, language changes, and downloads.
  6. Review the operating effort. Confirm that writers and administrators can maintain the rules during a normal release.

Bluestream’s XDelivery customer-service overview describes controlled access and personalized, localized content experiences. For your implementation, demonstrate which context comes from metadata, a user choice, or an integrated system, and how it is kept current.

Avoid personalization that hides useful information

Overly narrow filtering can hide the information needed to understand a problem. Give readers a clear way to inspect the scope of their results and broaden it when appropriate. Explain an empty result instead of making the collection appear broken.

Watch for conditional complexity. With several products, releases, platforms, roles, and languages, the number of combinations can grow quickly. Do not create every theoretical combination. Identify supported configurations and test those that matter, including changes to the shared content they use.

Do not duplicate whole manuals simply to change a few instructions. Equally, do not force reuse where the meaning differs. A short, audience-specific explanation may be easier to maintain safely than a sentence with many interacting conditions.

Collect only the context needed for the experience. A product selection may be enough without building a detailed behavioral profile. If account information or analytics is used, involve the appropriate privacy and security owners in deciding what is collected, retained, and exposed.

Measure relevance and maintainability

Compare users’ success on the same tasks before and after the pilot. Can they identify the correct product version? Do they complete the procedure without reading irrelevant steps? Can they recover when the initial filter is wrong?

Use search failures, repeated support questions, and reader feedback to understand the result. Fewer page views may mean readers reached the answer more directly; more page views may mean useful exploration or confusion. Usage counts need context.

Also measure the editorial cost. Record how long it takes to apply metadata, review variants, and correct a shared topic across releases. Personalization is sustainable when the reader benefit justifies that continuing work.

Expand the model when a new distinction solves a demonstrated problem. Clear metadata, reusable content, and visible user control create a more dependable experience than personalization added simply because a platform offers the feature.

Frequently asked questions

What is the simplest useful form of personalization?

A visible product, version, or language selector can provide immediate value. Start with context that changes which instructions apply and that readers can easily confirm.

Can DITA personalize content at runtime?

DITA can provide structure and metadata for targeted content. Runtime selection requires a compatible delivery implementation; many DITA workflows instead create variants during publishing.

Do we need separate topics for every audience?

No. Reuse shared material when its meaning remains the same, and create distinct content where the task, prerequisites, or explanation genuinely differs.

How do we stop personalization hiding the wrong material?

Show the active context, provide a way to change or broaden it, test missing and conflicting metadata, and review complete procedures for every supported variant.

Does personalization reduce support costs?

It can help readers solve problems, but the result depends on content quality and implementation. Measure relevant support issues and task success rather than assuming a guaranteed reduction.

Contact Us

Sign-up for the latest Bluestream News

Close